|
I am a postdoctoral researcher at Stanford University, advised by Prof. Jiajun Wu and Prof. Fei-Fei Li. I received my Ph.D. in EECS from UC Berkeley, advised by Prof. Ken Goldberg. My research focuses on general robot learning, particularly learning from human videos, real2sim2real transfer, and dexterous manipulation. I develop methods for scalable robot data generation, cross-embodiment world models, in-context imitation learning, and multimodal perception with touch. Email / Google Scholar / CV |
|
Honors and Service
- 2026: Microsoft Research Fellowship.
- 2026: Associate Editor, IEEE International Conference on Robotics and Automation (ICRA).
|
|
|
Huang Huang*, Wensi Ai*, Ziyu Chen*, Youhui Wang*, Zijian Du, Yang Liu, Jiaolong Yang, Li Fei-Fei, Jiajun Wu *Equal contribution arXiv 2026 · Website · Paper We convert simulated robot trajectories into photorealistic RGB videos while preserving geometry, robot motion, and action labels, enabling visual sim-to-real transfer for robot policies. |
|
|
Youhui Wang, Yunzhu Li, Li Fei-Fei, Jiajun Wu†, Huang Huang† †Equal advising arXiv 2026 · Website · Paper DexAgent turns a human demonstration video into dexterous robot training data through simulation reconstruction, trajectory optimization, and verification, using a self-evolving library of reusable tools. |
|
|
Zhi Cao*, Howard Ji*, Kevin Zhang*, Kuangzhi Ge, Li Fei-Fei, Jiajun Wu†, Huang Huang† *Equal contribution; †Equal advising arXiv 2026 · Website · Paper TrAct uses visual tracks as a shared interface between robot control and video prediction. It proposes action-track pairs, predicts their visual outcomes, and selects actions with a vision-language reward model. |
|
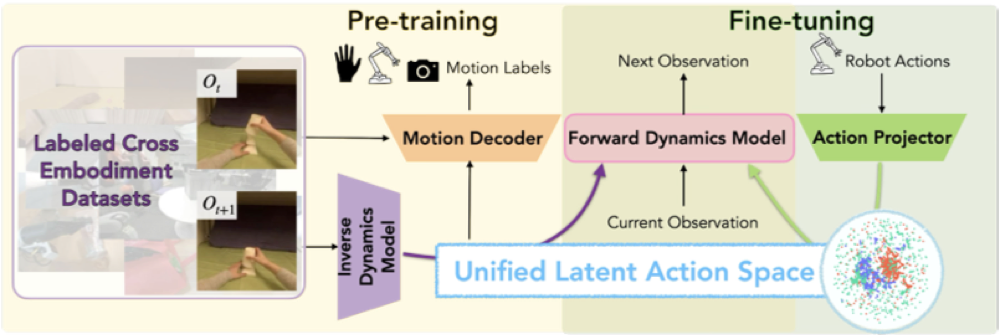 |
Huang Huang, Sriram Yenamandra, Arjun Majumdar, Elie Aljalbout, Tushar Nagarajan, Tsung-Yen Yang, Akshara Rai, Michael Rabbat, Li Fei-Fei, Jiajun Wu, Tingfan Wu, Franziska Meier ICML 2026 · Website · Paper We learn a shared latent action space for robot world models, enabling transfer across embodiments and improving downstream dexterous manipulation and other robot learning tasks. |
|
Justin Yu, Letian Fu, Huang Huang, Karim El-Refai, Rares Andrei Ambrus, Richard Cheng, Muhammad Zubair Irshad, Ken Goldberg CoRL 2025 · Oral Presentation · Website · Paper We generate robot training data from smartphone scans and human demonstration videos by reconstructing object geometry and motion, then rendering robot demonstrations. |
|
|
Huang Huang*, Fangchen Liu*, Letian Fu*, Tingfan Wu, Mustafa Mukadam, Jitendra Malik, Ken Goldberg, Pieter Abbeel *Equal contribution ICML 2025 · Website · Paper OTTER extracts task-relevant visual features aligned with language instructions from frozen vision-language encoders, improving generalization to unseen robot manipulation tasks. |
|
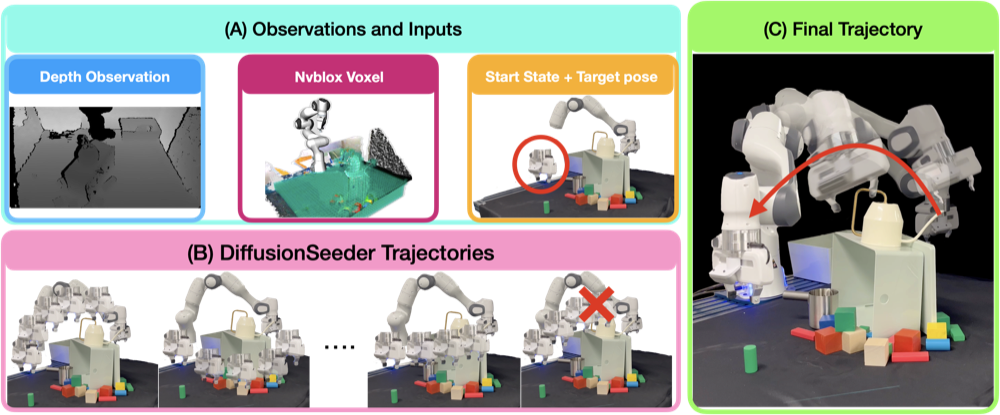 |
Huang Huang, Balakumar Sundaralingam, Arsalan Mousavian, Adithyavairavan Murali, Ken Goldberg, Dieter Fox CoRL 2024 · Website · Paper We use diffusion models to generate diverse trajectory seeds for motion optimization, enabling rapid robot motion planning. |
|
|
Letian Fu*, Huang Huang*, Gaurav Datta*, Lawrence Yunliang Chen, William Chung-Ho Panitch, Fangchen Liu, Hui Li, Ken Goldberg *Equal contribution ICRA 2025, Website We explore how to enhance next-token prediction models to perform in-context imitation learning on a real robot. We propose In-Context Robot Transformer (ICRT), a causal transformer that generalizes to unseen tasks conditioned on prompts of sensorimotor trajectories of the new task composing of image observations, actions and states tuples, collected through human teleoperation. |
|
Letian Fu, Gaurav Datta*, Huang Huang*, William Chung-Ho Panitch*, Jaimyn Drake*, Joseph Ortiz, Mustafa Mukadam, Mike Lambeta, Roberto Calandra, Ken Goldberg *Equal contribution ICML 2024, Oral Presentation, Website We introduce the Touch-Vision-Language (TVL) dataset, which combines paired tactile and visual observations with both human-annotated and VLM-generated tactile-semantic labels. We then leverage a contrastive learning approach to train a CLIP-aligned tactile encoder and finetune an open-source LLM for a tactile description task. Our results show that incorporating tactile information allows us to significantly outperform state-of-the-art VLMs (including the label generating model) on a tactile understanding task. |
|
|
Huang Huang, Antonio Loquercio, Ashish Kumar, Neerja Thakkar, Ken Goldberg, Jitendra Malik ICRA 2024, Website For locomotion, is an arm on a legged robot a liability or an asset for locomotion? Biological systems evolved additional limbs beyond legs that facilitates postural control. This work shows how a manipulator can be an asset for legged locomotion at high speeds or under external perturbations, where the arm serves beyond manipulation. |
|
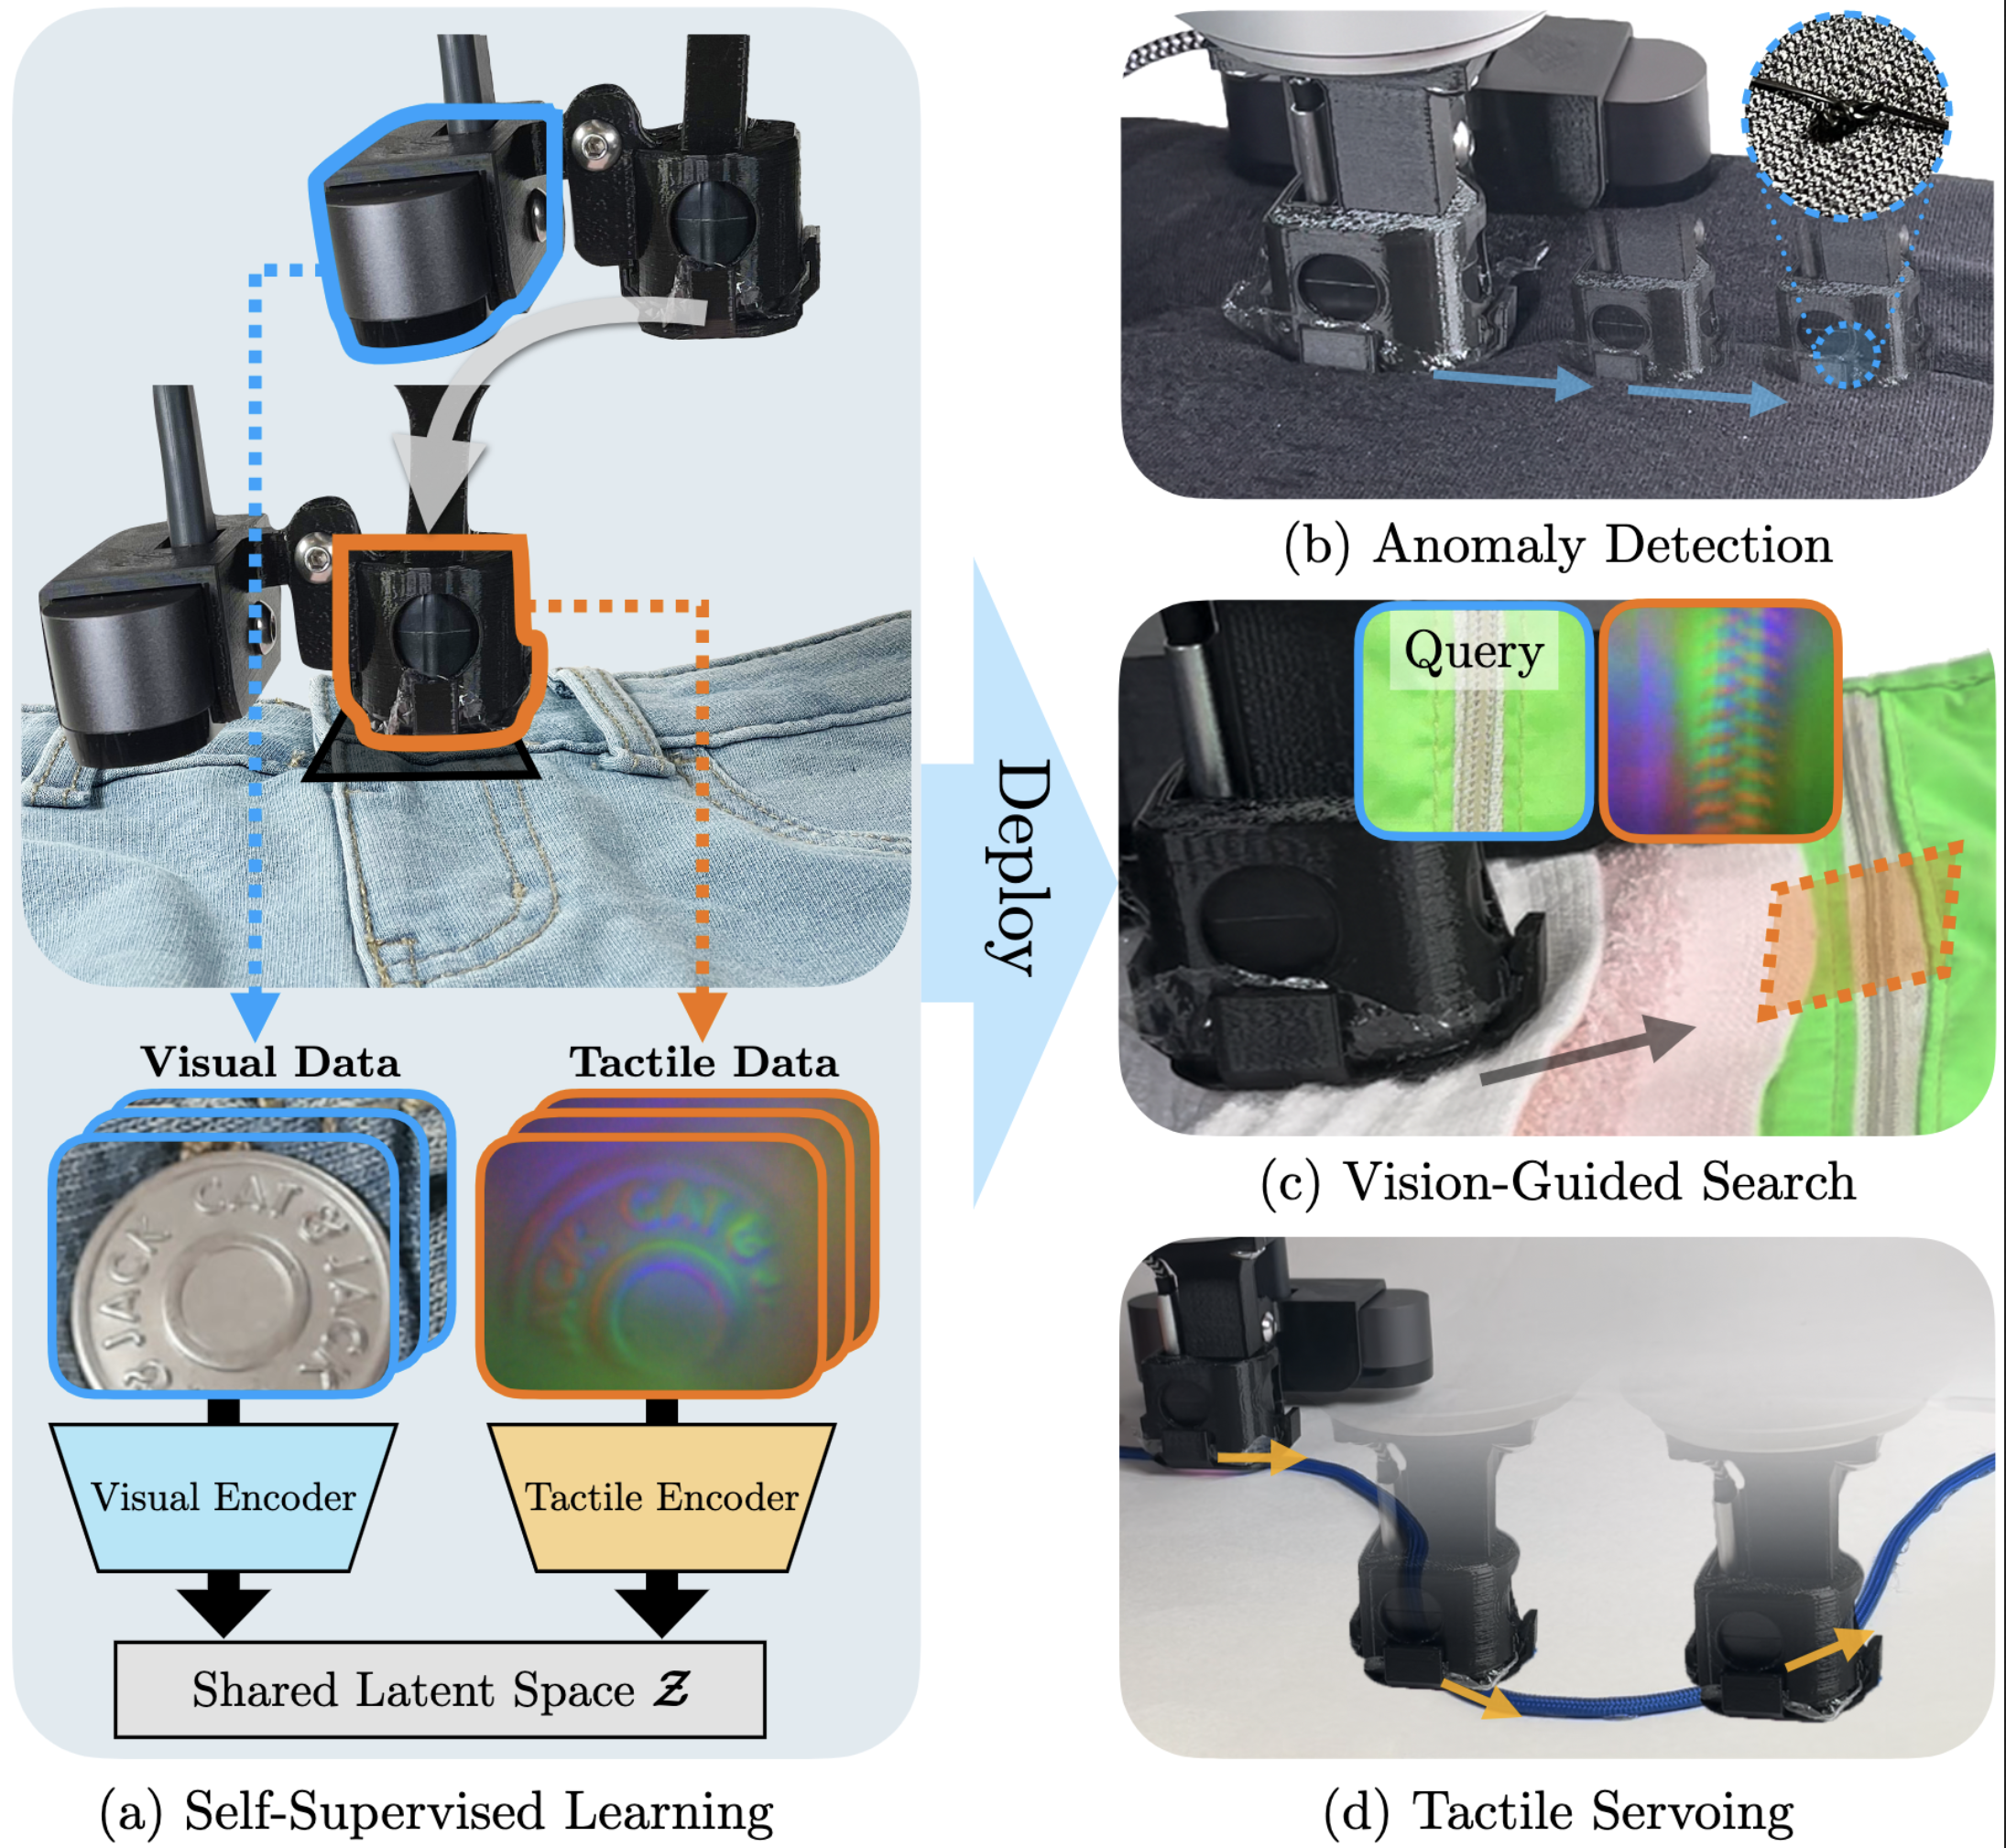
Justin Kerr*, Huang Huang*, Albert Wilcox, Ryan Hoque, Jeffrey Ichnowski, Roberto Calandra, and Ken Goldberg, *Equal contribution RSS 2023, Paper We learn self-supervised representations from vision and touch using contrastive learning. The representations support active perception of deformable surfaces without task-specific fine-tuning. |
|
|
Justin Kerr, Letian Fu, Huang Huang, Yahav Avigal, Matthew Tancik, Jeffrey Ichnowski, Angjoo Kanazawa, Ken Goldberg CoRL 2022, Oral Presentation, OpenReview We propose Evo-NeRF with additional geometry regularizations improving performance in rapid capture settings to achieve real-time, updateable scene reconstruction for rapidly grasping table-top transparent objects. We train a NeRF-adapted grasping network that learns to ignore reconstruction artifacts. |
|
|
Vincent Lim*, Huang Huang*, Lawrence Yunliang Chen, Jonathan Wang, Jeffrey Ichnowski, Daniel Seita, Michael Laskey, Ken Goldberg, *Equal contribution ICRA 2022, paper We collect planar robot casting data in real in a self-supervised way to tune the simulation in Isaac Gym. We then collect more data in the tuned simulator. Combined with upsampled real data, we learn a policy for planar robot casting to reach to a given target, attaining median error distance (as % of cable length) ranging from 8% to 14%. |